
Do We Buy It or Build It?
When attending conferences or even chatting casually with peers across other institutions, I increasingly hear some version of the agent-era dilemma, “Do we buy this or build it?” You can absolutely build many great things now.
But should you?
I recently developed a textbook platform that I could use for one of my courses, despite already having access to an OER publishing platform. I still use my college’s official platform for most of my OER work, but for this one course, I’ve been itching to incorporate more artifacts and interactions that require the platform to be agent-native. Perhaps the official publishing platform will get there one day, who knows, but I felt constrained so I vibe-coded my own agent-native publishing platform.
When going back and forth with Codex about this idea, I said I wanted a kind of cross between what I could do on Substack and something like Pressbooks, LibreTexts, or OpenStax, but built from the ground up to support agentic interactions, which meant incorporating a robust API, supported by MCPs and agent skills. There’s also a somewhat new WebMCP standard that I want to experiment with.
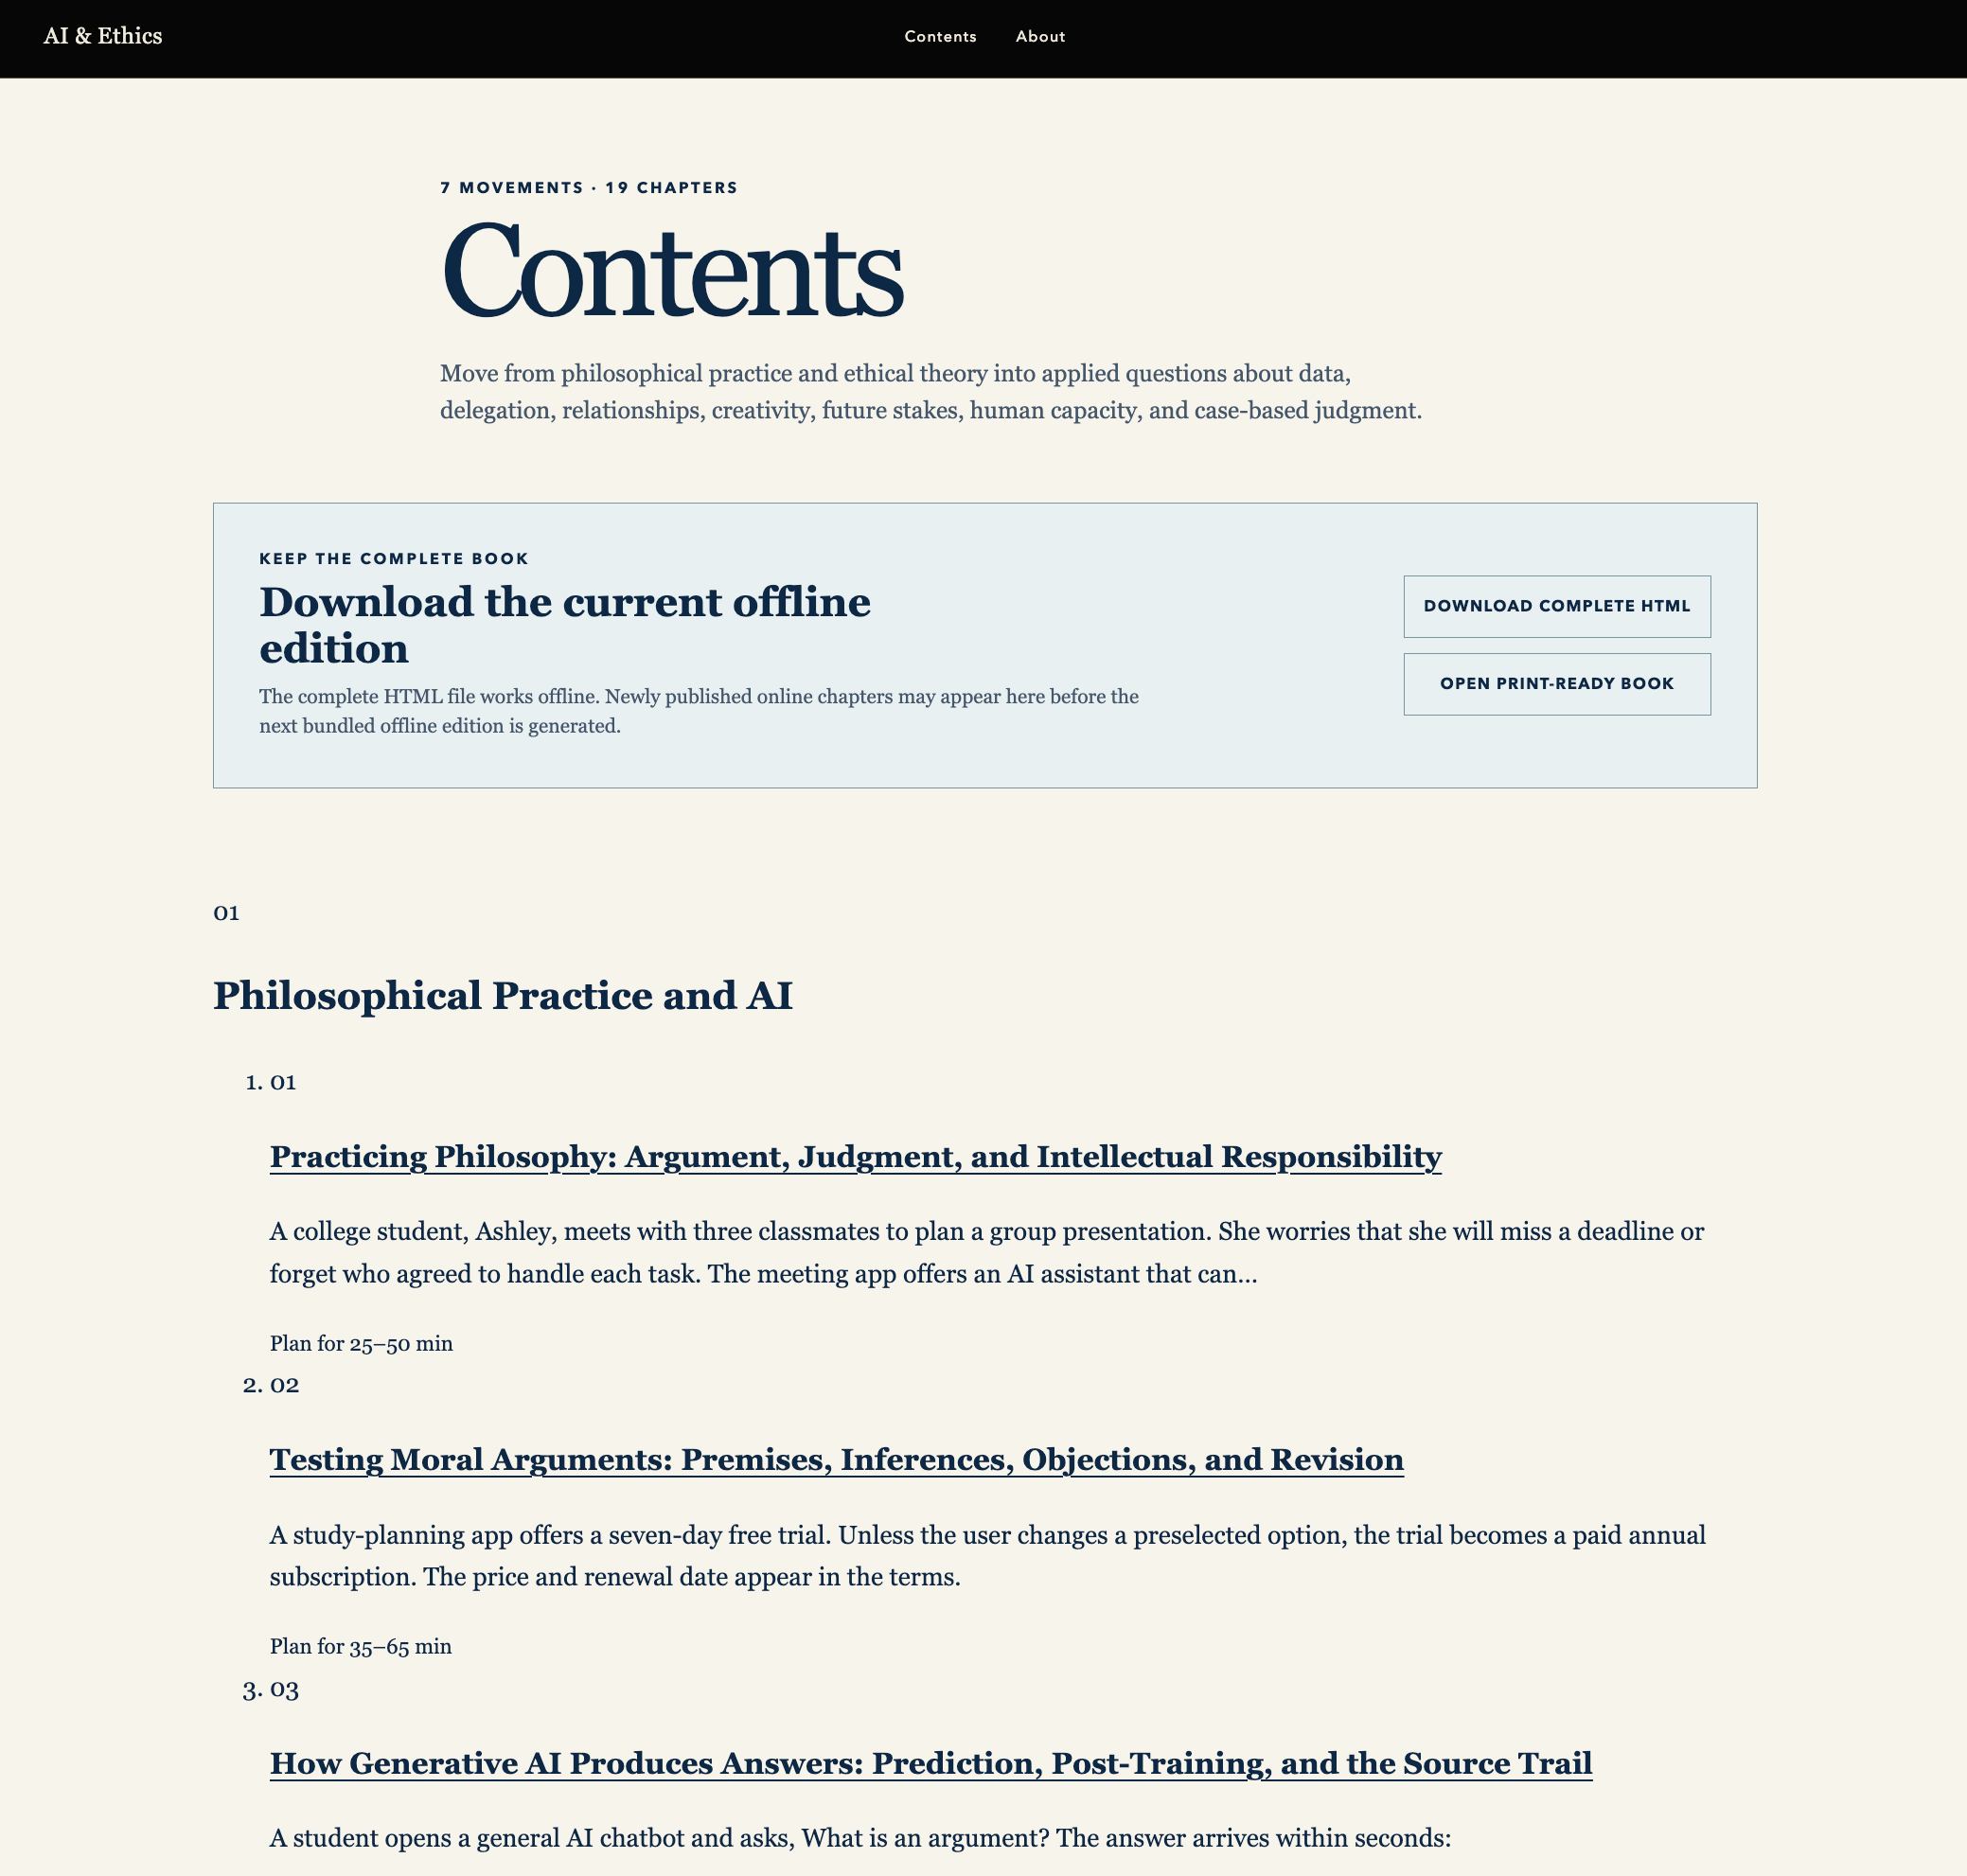
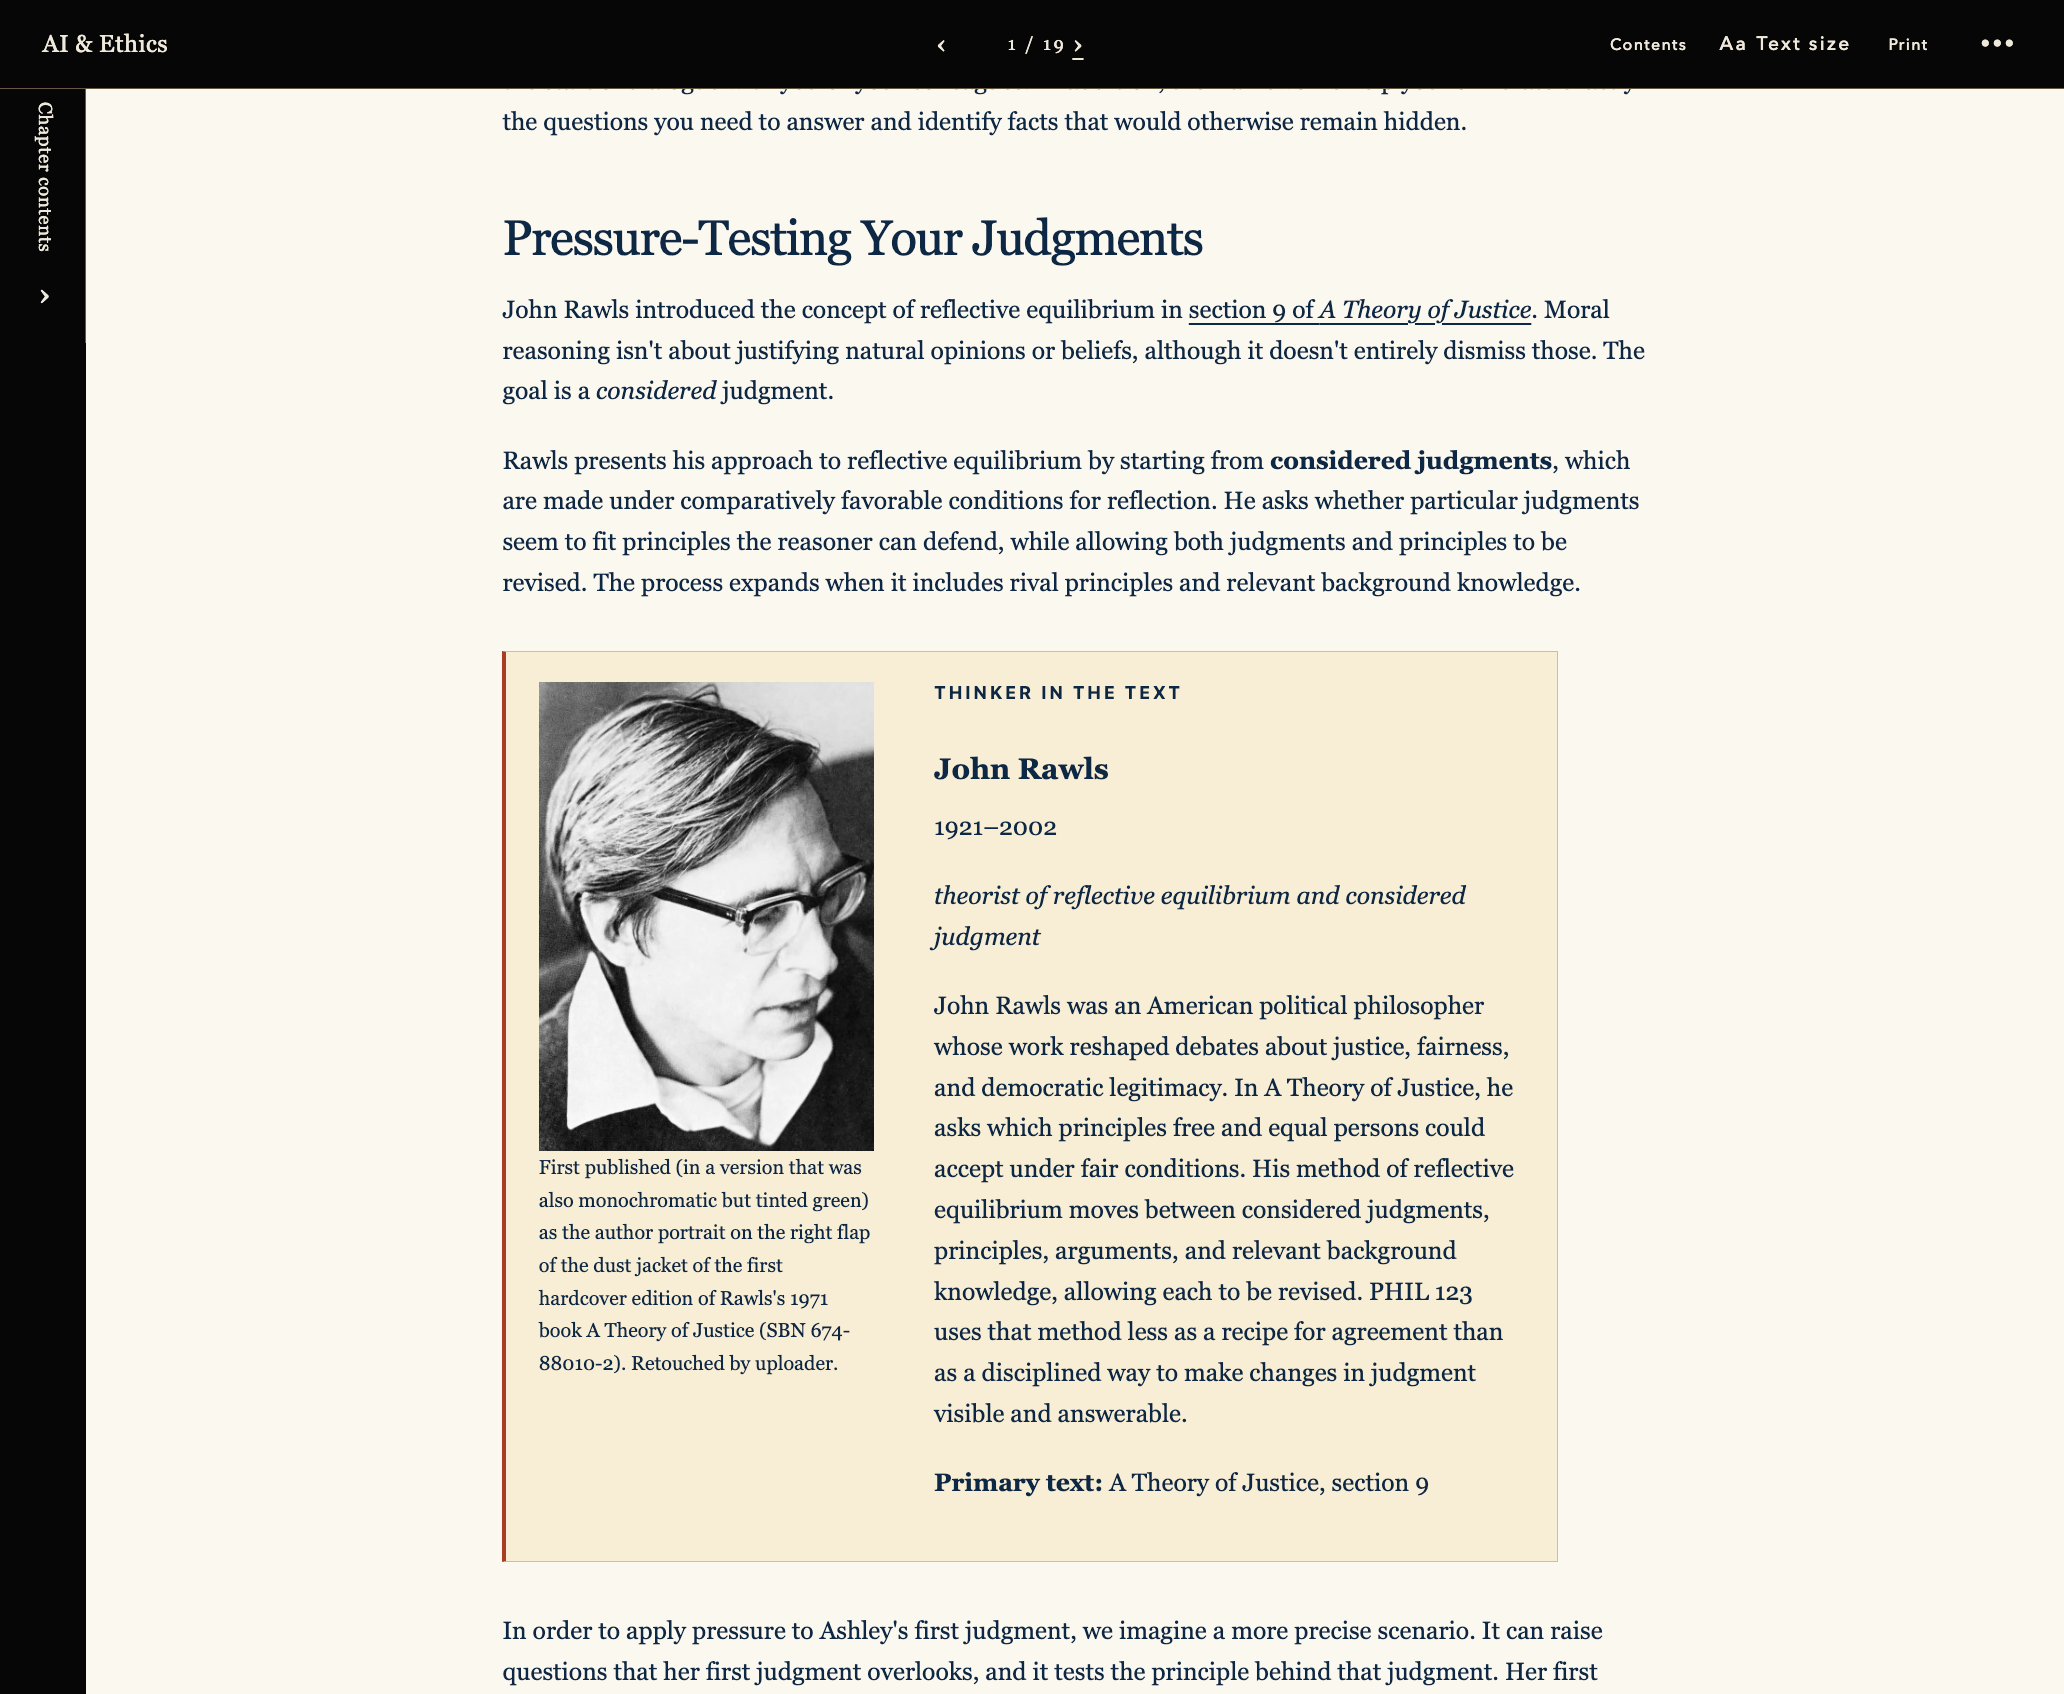
I learned a lot building this out. In the process, I discovered that many of these platforms are built on top of WordPress, while the source code lives on GitHub. All this seemed perfectly doable. So I “just” poured billions of tokens into building my own platform, connecting GitHub for the basic infrastructure and Cloudflare for hosting the content. Now I can log in using my GitHub account and then edit chapter by chapter, add images, etc. Since I developed this to be agent-native, I usually only use the editing pane for updating the prose and let Codex or Claude Code manage everything else. The benefits are 1) speed, 2) token efficiency, and 3) the ability to incorporate interactions that would never work on other publishing platforms. I can add reflective checkpoints for students and seamlessly add coded artifacts and activities that would be too complicated to host on another publishing platform. And of course accessibility-related workflows become much smoother.
Here are a few screenshots. I’ve come to deplore the landing page’s AI image slop but am overall fairly content with what it does.
I really love working with this platform now but it’s been a nightmare to maintain.
For one, it’s not cheap. I’m paying for a ChatGPT Max subscription that allows me to tinker so much. I also have to maintain Cloudflare hosting, which can cost extra money depending on how much data is being maintained. If you count my subscription, the Cloudflare expenses, and especially the time involved, it’s definitely not saving me money.
Despite these headaches and expenses, it serves a very specific need that I can’t get with existing platforms. Perhaps over time it will be worth it?
Idaho colleges are starting to build more
I see my own dilemma playing out across Idaho.
Last year I served as the lead for the Idaho State Board’s AI Catalyst Initiative. We trainings and provided support for faculty to become AI-ready. In the process, I learned a lot about AI-related problems that tend to plague many campuses.
For example, despite the fact that all Idaho public higher eds have some kind of partnership with either Google Gemini or Microsoft CoPilot, what you can actually do with these AI stacks is severely constrained. One of the simplest tech solutions right now should be for faculty to create custom chatbots and share those with students, yet even that very limited function may not be available because the creator’s license, the recipient or student license, the tenant or admin settings, and the permissions on every source file all have to line up with how the subscriptions and accounts work at our institutions. Gemini and Copilot are technically included in all of our lowest tiers, but it’s often a nightmare when trying to do anything sophisticated with those accounts.
The dilemma our campuses face is whether to partner with different chatbot platforms or developing our own solutions with the help of Claude Code (usually), Codex (sometimes), or Antigravity (rarely but still happens).
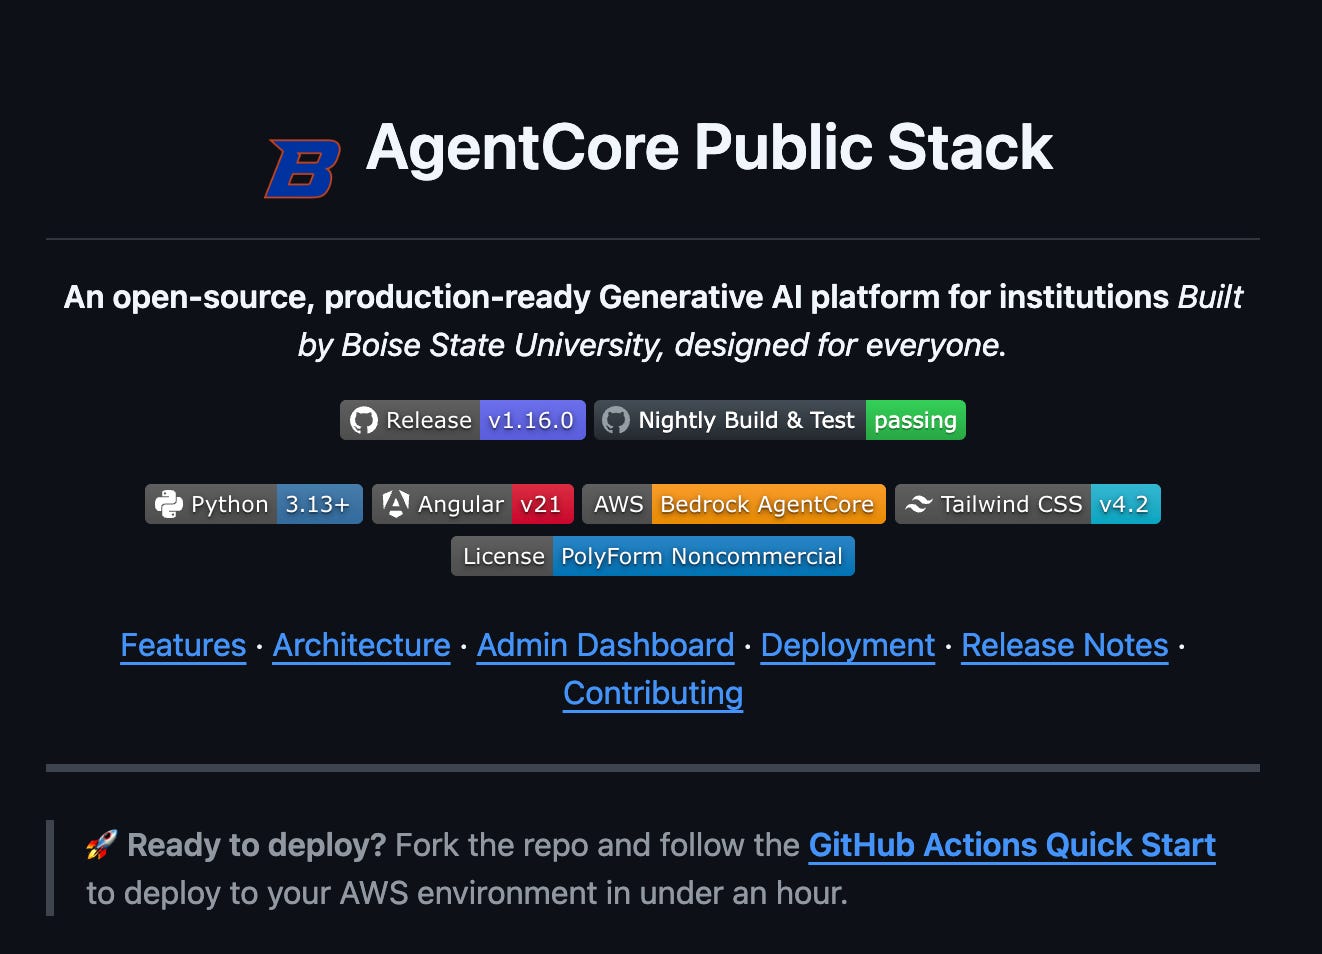
Boise State University is the most well-known example developing their own chatbot infrastructure. They still partner with some edtech companies that provide chatbot services, but they’ve developed their own version called Boise State AI Chat. It provides an infrastructure that allows faculty, staff, and students to select from a variety of APIs. If you’re interested, the public repository behind boisestate.ai shows how this works. A web chat and admin dashboard sit on AWS Bedrock AgentCore and Strands Agents in an institution-controlled AWS deployment. The stack includes role-based model access, quota tiers, token-level cost tracking, and separately deployed MCP integrations. But what’s really nice (and what makes it bespoke) is that the MCPs are designed to connect these models to campus systems and data. It’s become much more than simply a “custom chatbot” platform.
University of Idaho has an excellent model setup called MindRouter, where anyone with a Vandal account can sign in from the campus network or VPN. VandalChat is the chatbot layer. Underneath it, MindRouter is a local inference gateway that translates calls from common OpenAI, Ollama, and Anthropic APIs, all while enforcing per-user quotas.
I know of a professor at another college who’s developing a custom chatbot platform, somewhat similar to Boise State AI, but relying entirely on local models.
To be clear: all of this work is happening because faculty and staff at these institutions have access to powerful coding agents (usually Antigravity, Claude Code, or Codex) and have a clear vision of how they might develop their own AI solutions. Some of this is being built by faculty, not traditional software developers. Other pieces are being built by software developers who work heavily with Claude Code or Codex.
None of this is being built by traditional software developers who aren’t using agent harnesses.
When it makes sense to partner
In some cases, I’ve noticed it’s actually cheaper and safer to partner with an edtech company that specializes in certain products, such as a company that provides custom chatbots. Depending on a campuses budget and how much they need to scale access, it often doesn’t make sense to develop a bespoke chatbot service. The key players in this chatbot space usually have partnerships with AI companies or are grant-funded in ways that allow them to provide a low-cost solution for just custom chatbots. A well-funded edtech company that specializes in a single solution often makes more sense than pouring vibe-coding time into a custom solution. Agent-assisted development isn’t cheap! Aside from token or subscription access, it requires a lot of time and long-term maintenance. Time (calculated from the faculty or staff member’s salary) can be the largest hidden expense.
The other issue is whether the AI interaction involves campus data or collects PII. Many campuses have multiple CRMs now, for different parts of the student lifecycle. It seems perfectly reasonable to vibe-code a specialized CRM rather than partner with yet another provider. But the combination of PII and connecting with other institutional data pipelines raises the stakes for how carefully the software needs to be developed and maintained.
My rules for when to (vibe) build it
If a campus is deciding how much to get serious with building their own tech stack, here’s what I recommend right now:
Invest in faculty and staff who have a knack for working with agents. Sometimes this will be obvious. But I suspect much of the talent is hidden right now. I’ve personally observed that some of the most talented agent-assisted developers work under the radar because institutions don’t officially partner with Claude Code or Codex. Pour resources into these talented individuals. Give them time and access to tokens. Let them cook. Yes all faculty and staff need training and support, but there shouldn’t be a choice between investing in the most talented individuals and scaling access. The campuses I see doing innovative things right now owe a great deal to just a few key faculty or staff members who have vision and talent. And keep in mind that who can provide innovative solutions for an institution is no longer determined by role. Some of your best instruction-facing tech solutions will not be built (at least initially) by your campuses software developers.
Depending on the position or discipline, hire for people who are savvy with these agentic platforms. I would even extend this to faculty. Perhaps it doesn’t make sense to hire for agent-savviness in the humanities (there are exceptions though!), but some of the most talented edtech developers right now are faculty who understand instructional needs and can code with agents. Most traditional software developers are very deficient at understanding what faculty actually need. We all feel this when using edtech software, it’s extremely painful. We’re now seeing that somewhat technical faculty can develope far more useful software than what’s being pitched by many traditional edtech platforms.
Go hard on vibe-coding in low-risk situations. If the interactions don’t collect PII or connect with the institution’s data, there should be enormous incentives around vibe-coding right now, mainly because it fosters a culture of self-sufficiency and allows an institution to develop these instincts. Most of these experiments will fail. Most prototypes will be awful. Tokens will be wasted. In the long-term, it will be worth it. Campuses who rely entirely on enterprise partnerships to solve all their problems will feel safer in the short term only to find themselves even more reliant and budget-constrained over time.
The best solutions often happen through faculty or staff prototypes that eventually get audited and perfected by the campuses software dev team. Encourage these partnerships and figure out ways to streamline protocols so innovative individuals who aren’t officially part of IT can more efficiently partner with IT’s software dev teams. Instruction vs. IT divides is one of the key bottlenecks I’m seeing right now.
My rules for when to not build it
There are exceptions.
This is covered above, but it’s fairly obvious that software that involves PII & institutional data is a separate category of vibe-coding. To be clear, 90% of campus software is agent-assisted now, but data-sensitive software has to be maintained by actual software developers who understand tech audits and cybersecurity. This doesn’t mean non-devs can’t prototype a bespoke CRM. But it should be treated as just proof of concept that needs to be fully developed by actual developers.
Some legacy and enterprise software is better just because it’s shared. This takes me back to the OER textbook platform dilemma. Yes you can develop your own platform now but scaling it will probably cost just as much as paying for one of the existing providers and there’s enormous benefits in working with a tech stack that others use. Over the summer I delivered a keynote at the CalOER conference, where most faculty used LibreTexts. Having that common tech experience allowed them to focus their AI + OER trainings and created a sense of community. This is true of other software. I’ve developed my own writing editor to be more agent-native than Google Docs or Microsoft Word, but side-projects like that are mostly a waste of time for institutions unless it can scale. We need to be able to share and review each’s other work very easily.
As a coda, I should point out that you’re likely to see more “build it” experiments coming out of Idaho over the next few years in part due to Liza Long’s (Artisanal Intelligence) efforts at the Idaho Office of the State Board of Education. In 2025, OSBE won a $4 million FIPSE grant, thanks to Liza’s proposal, and most of that is being passed along to the eight public higher eds across Idaho to fund AI-readiness efforts. Some of the best sub-grant proposals we’re seeing are strong examples of how our Idaho institutions are choosing to build local AI solutions.